Global LLM Benchmark Ranking 2026
As of 2026-10-14. Arena Text (2026-10-13) filtered: non-Preliminary & votes≥10,000. Claude Opus 4.6 (high) 1503±3 first by tie-break votes.
Compiled 2026-10-14. The main table filters Arena Text Overall (2026-10-13): drop Preliminary and rows under 10,000 votes. Among stable rows, Claude Opus 4.6 (high) and Fable 5 (high) tie at 1503 Elo — more votes put Opus 4.6 (high) first. Gemini 4 Argon stays on the watch table despite leading the raw board.
Arena stable sample (votes ≥10,000, non-Preliminary)
Elo ± copied from Arena. Ties: more votes, then narrower CI. Overlapping intervals are not narrated as clear wins.
| # | Model | Vendor | Arena Elo | Votes |
|---|---|---|---|---|
| 1 | Claude Opus 4.6 (high) | Anthropic | 1503±3 | 80,827 |
| 2 | Claude Fable 5 (high) | Anthropic | 1503±4 | 41,439 |
| 3 | Claude Opus 4.7 (high) | Anthropic | 1501±4 | 65,125 |
| 4 | Claude Fable 5.1 (max) | Anthropic | 1501±6 | 14,121 |
| 5 | Claude Opus 4.6 | Anthropic | 1498±3 | 85,445 |
| 6 | Claude Opus 4.7 | Anthropic | 1494±4 | 66,213 |
| 7 | Muse Spark 1.3 (max) | Meta | 1494±6 | 16,731 |
| 8 | Claude Opus 5 (high) | Anthropic | 1490±4 | 65,663 |
| 9 | Muse Spark 1.1 | Meta | 1490±4 | 41,938 |
| 10 | Claude Opus 5 (max) | Anthropic | 1490±5 | 31,907 |
| 11 | Muse Spark | Meta | 1489±6 | 14,163 |
| 12 | Kimi K3 (max) | Moonshot | 1488±5 | 32,036 |
| 13 | Gemini 3.1 Pro Preview | 1487±3 | 126,781 | |
| 14 | Gemini 3 Pro | 1485±4 | 42,088 | |
| 15 | GPT-5.6 Sol (xhigh) | OpenAI | 1485±4 | 39,832 |
Watch table: Preliminary or low votes
| Board # | Model | Vendor | Elo | Votes | Why not in main |
|---|---|---|---|---|---|
| 1 | Gemini 4 Argon (high) | 1525±9 | 4,903 | Preliminary | |
| 2 | Muse Wonder Max | Meta | 1513±13 | 1,944 | Votes < 10,000 |
| 3 | Claude Opus 5.5 (high) | Anthropic | 1508±8 | 7,687 | Votes < 10,000 |
| 9 | Gemini 3.8 Flash (high) | 1496±5 | 35,670 | Preliminary | |
| 10 | Muse Spark 1.2 (xHigh) | Meta | 1495±7 | 7,611 | Votes < 10,000 |
| 18 | Gemini 3.7 Flash (high) | 1487±5 | 26,328 | Preliminary | |
| 22 | GPT-6.1 Sol (max) | OpenAI | 1484±8 | 5,762 | Votes < 10,000 |
Artificial Analysis Intelligence Index
| # | Configuration | Vendor | Intelligence Index |
|---|---|---|---|
| 1 | Claude Opus 5.5 (max + fallback) | Anthropic | 58 |
| 2 | Claude Sonnet 5.5 (max + fallback) | Anthropic | 56 |
| 3 | Muse Wonder Full (max) | Meta | 56 |
| 4 | Claude Fable 5.1 (max + fallback) | Anthropic | 53 |
| 5 | GPT-6 Astra (max) | OpenAI | 53 |
| 6 | Gemini 4 Argon (high) | 53 | |
| 7 | GPT-6.1 Sol (max) | OpenAI | 52 |
| 8 | Muse Spark 1.3 (max) | Meta | 48 |
| 9 | Grok 4.7 (xhigh) | xAI | 46 |
How this ranking was built
Compiled 2026-10-14. Arena board 2026-10-13. The main table is not a raw 1–N copy: we drop Preliminary rows and rows with <10,000 votes (moved to the watch table), then sort by Elo descending; ties break by more votes, then narrower ±CI. Elo figures stay copied from Arena — no invented decimals. Overlapping CIs are not narrated as clear wins. AA Intelligence Index is a separate synthetic ruler. See also ability and coding models.
| Source | Snapshot | Scope | Weight |
|---|---|---|---|
| Arena Text Overall | 2026-10-13 | Filter: non-Preliminary & votes ≥10,000; tie-break votes→CI | Primary |
| Same (watch table) | 2026-10-13 | Preliminary or votes <10,000; keep board # | Support |
| AA LLM Leaderboard | 2026-10-14 | Intelligence Index; best config per line | Support |
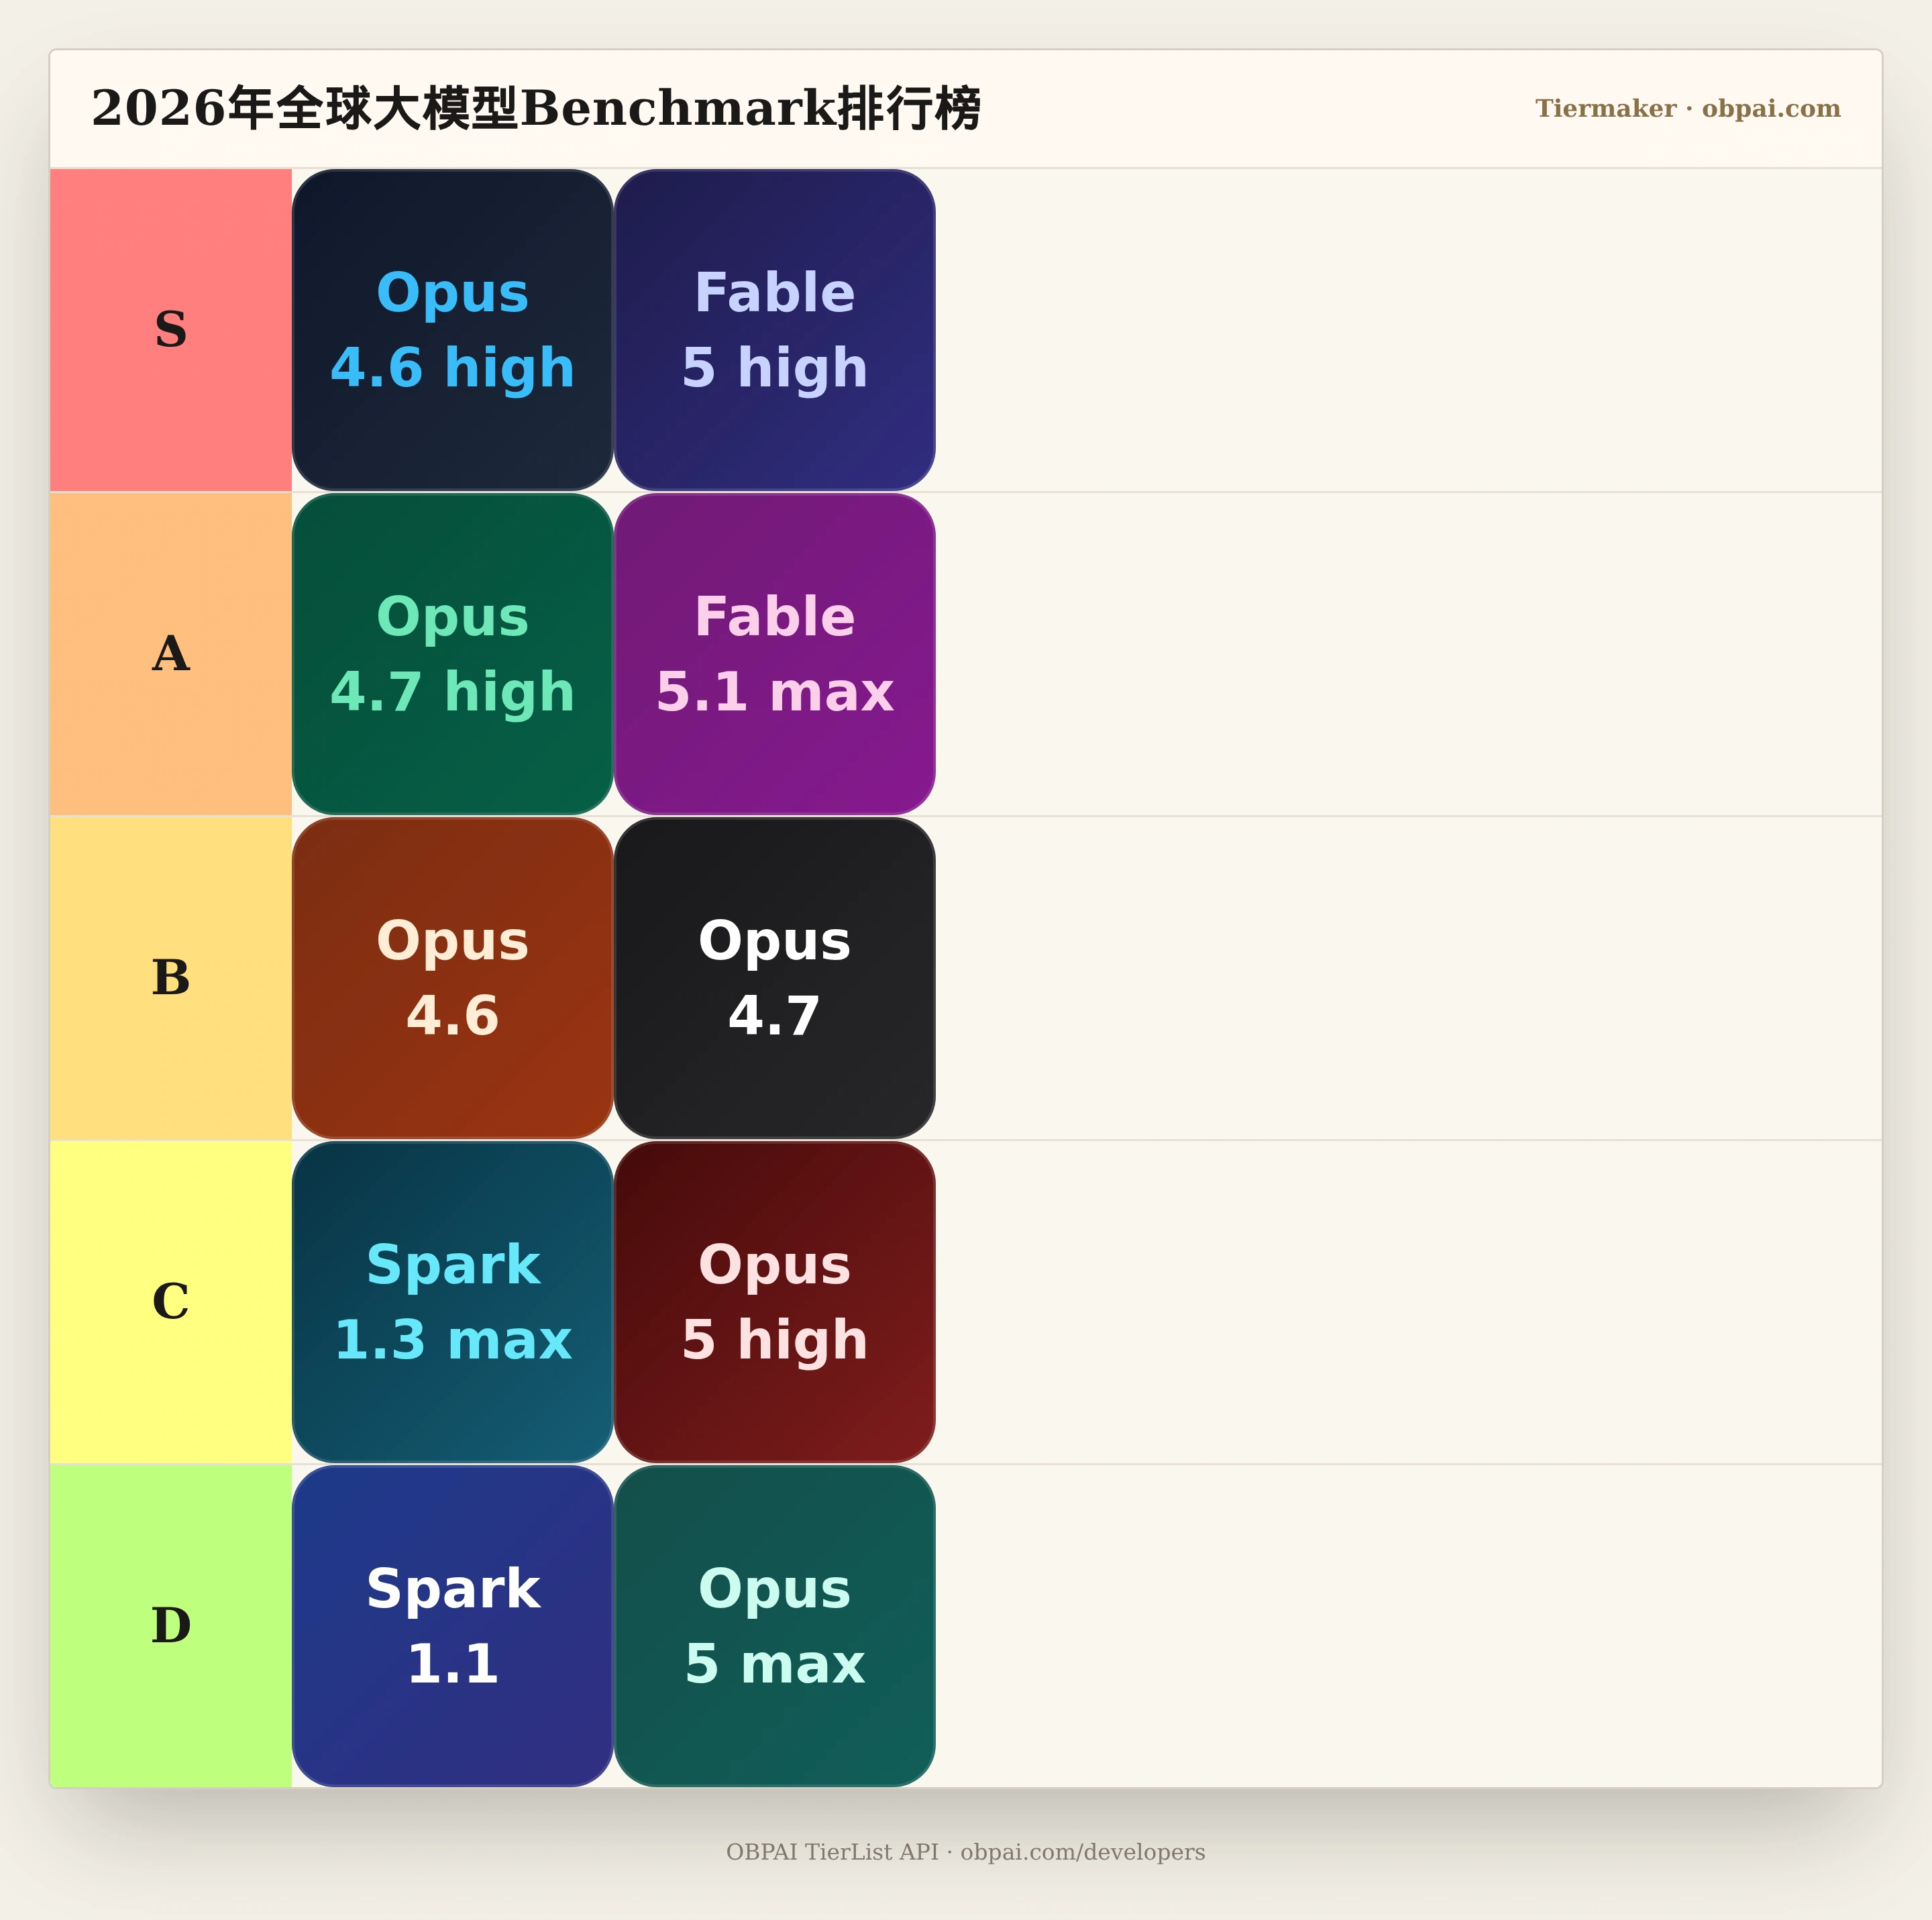
互动体验:拖拽排位《LLM Benchmark Tier List 2026》
LLM Benchmark Tier List 2026
想打造自己的个性化天梯图并开放给读者嵌入吗?